ByteDance Seedance 2.5 Launches With 30-Second Native AI Video Clips — What Creators Need to Know
Get The Faceless YouTube Blueprint — Free
The exact AI tool stack and workflow used to build a faceless YouTube channel from zero.
ByteDance Seedance 2.5 Launches With 30-Second Native AI Video Clips — What Creators Need to Know
⚡ Expert Summary: ByteDance launched Seedance 2.5 in early July 2026, claiming a major breakthrough: native 30-second AI video clips in a single generation pass — no stitching, no scene cuts, no visible seams. The model also handles up to 50 multimodal references, 4K output, and unified audio-video generation. For content creators, this changes what is possible with AI video. But the Hollywood copyright cloud over ByteDance means adoption carries risk.
The hardest problem in AI video generation has always been duration. Every model could produce impressive five-second clips. Some could push to ten seconds. A few reached fifteen. But every clip beyond ten seconds suffered from the same degradation: characters drifted, lighting shifted without cause, and motion lost coherence. The result was unusable for anything requiring sustained narrative.
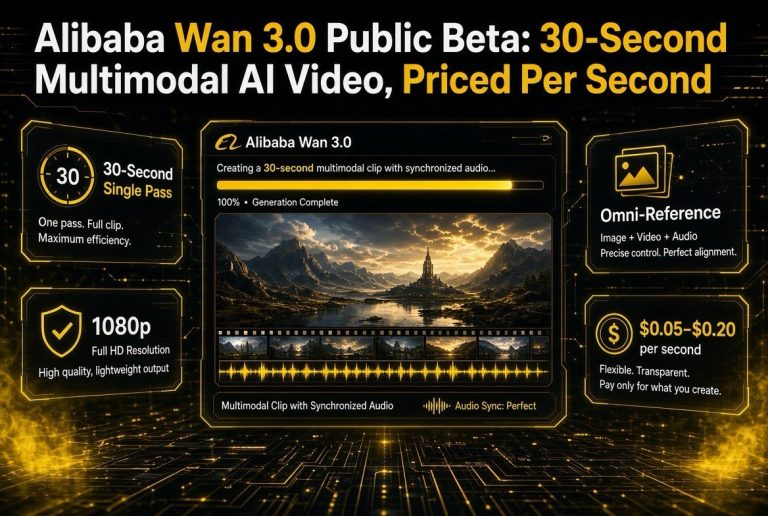
ByteDance claims Seedance 2.5 has solved this. The model, which launched in early July 2026 through ByteDance’s Dreamina and Jimeng platforms, generates continuous 30-second video clips in a single pass. No segment stitching. No scene-cut splicing. No visible seams between shorter clips.
If the claims hold up under independent testing, this is the most significant technical advance in AI video since the first ten-second models emerged in 2024.
How Seedance 2.5 Generates 30 Seconds Without Stitching
The engineering problem Seedance 2.5 claims to have solved is not simply making clips longer. Every AI video generator that has pushed past ten seconds has hit the same constraint: temporal coherence degrades over time. A character face drifts subtly between frames. Lighting conditions shift without cause. A hand that appears in frame five looks like a different hand in frame twenty-two.
The standard industry workaround has been segment stitching: generate several shorter clips independently, then join them in post-production. The joins are invisible to a casual viewer but detectable to trained eyes, AI detection tools, and anyone trying to maintain consistent character appearance across a multi-shot sequence.
Seedance 2.5 addresses this at the architecture level. The model uses a Sparse Diffusion Transformer framework developed by ByteDance Doubao team, with an optimized sparse attention mechanism. Where earlier diffusion models processed video frames with attention windows limited to shorter temporal spans, the sparse Diffusion Transformer approach allows the model to maintain coherent scene state across the full clip duration in a single inference pass.
The audio architecture is equally significant. Seedance 2.5 uses a unified joint audio-video generation system where visual and auditory signals are co-processed inside the same latent space. Audio is generated in parallel with the video rather than fitted as an afterthought. Dialogue, ambient sound, and music cues stay in sync across the full clip without manual correction.
What Changed From Seedance 2.0
The version numbering signals a generational leap. ByteDance skipped versions 2.1 through 2.4 entirely, jumping from 2.0 to 2.5.
Seedance 2.0 could generate clips of up to 15 seconds natively. To reach 30 seconds, it required sequential stitching generating multiple shorter segments and joining them in post. Seedance 2.5 produces the full 30 seconds in a single generation call.
The multi-reference input is another major upgrade. Seedance 2.5 accepts up to 50 multimodal reference inputs: images, videos, audio clips, and text prompts combined in a single generation. For a creator building a consistent character or product across shots, this means uploading multiple reference images of the subject and the model maintains consistency across every generated frame.
Resolution has also been pushed to native 4K output. Earlier versions upscaled from lower resolutions. Seedance 2.5 generates at 4K natively, which eliminates the upscaling artifacts and detail loss that plagued earlier models.
The unified audio-video generation is a first for major AI video models. Google Veo 3 added native audio earlier in 2026, but Seedance 2.5 co-processes audio and video in the same latent space from the start, theoretically producing better synchronization than post-hoc audio fitting.
What This Means for Content Creators
For creators who have been working with AI video tools, the jump from 15-second to 30-second native clips is transformative for several use cases.
Narrative storytelling. Thirty seconds is long enough for a complete micro-scene. A character can deliver a line, react, and move to the next beat. Short-form platforms like YouTube Shorts, Instagram Reels, and TikTok all support clips at or above 30 seconds. A single Seedance 2.5 generation can fill an entire short-form video without any editing.
Product demonstrations. A thirty-second continuous shot can show a product from introduction through key feature highlights to a closing frame. The unified audio means voiceover and sound effects are generated with the visual, eliminating the sync work that currently consumes hours of post-production.
Ad creative generation. Thirty-second spots are the standard length for digital video ads. Seedance 2.5 allows advertisers to generate draft ad concepts in a single generation call rather than assembling multiple shots. For agencies testing creative directions, this cuts concept development from days to minutes.
Multi-shot consistency. With up to 50 reference inputs, creators can maintain character and environment consistency across multiple 30-second generation runs. A character introduced in the first clip can look identical in the tenth, because each generation references the same source images.
The Copyright Cloud That Should Give Creators Pause
Seedance 2.5 technical capabilities are impressive. But every major Hollywood studio has sent cease-and-desist letters over Seedance predecessor models. The copyright question is not theoretical.
ByteDance operates under Chinese law, which means the company must comply with China national intelligence requirements regardless of where content is generated. This creates a legal vulnerability for US creators: content generated through Seedance 2.5 passes through servers subject to Chinese jurisdiction. For commercial projects with copyright concerns, intellectual property protection, or client confidentiality requirements, this is a real risk.
The practical question for creators is straightforward: are you generating throwaway social media content, or are you generating assets that need legal protection? For the former, Seedance 2.5 is a powerful and increasingly affordable tool. For the latter, you need to understand the copyright and data jurisdiction implications before committing to the platform.
How Seedance 2.5 Compares to the Competition
The AI video landscape in mid-2026 is more competitive than ever. Here is how Seedance 2.5 stacks up against the alternatives:
Google Veo 3.1 remains the leader for cinematic quality and prompt adherence. Veo output looks more polished for narrative scenes with complex lighting and camera movement. But Veo is capped at shorter clip durations and lacks the multi-reference input depth of Seedance 2.5.
Kling 3.0 is strong on stylized output and character consistency, with native 4K and audio sync. Kling competes directly with Seedance on features, but the 30-second native generation is unique to Seedance 2.5 as of July 2026.
Runway Gen-4 offers superior creative controls — motion brushes, timeline editing, Director Mode — that make it the best tool for iterative refinement. But Runway clips are shorter and require more manual assembly for extended sequences.
OpenAI Sora is essentially out of the picture. Sora 2 saw significant platform changes and discontinuation in early 2026, with the web and app experiences ending around April. Users have largely migrated to alternatives.
Seedance 2.5 unique advantage is length and reference depth. If your project needs sustained continuous clips or complex multi-character consistency, Seedance is the strongest option. If you need polished cinematic output or granular editing control, Veo or Runway may serve you better.
Practical Steps for Creators Evaluating Seedance 2.5
Access is rolling out through Dreamina for international users and Jimeng for the China market, with CapCut integration expected soon and API access through Volcano Engine following later. For creators evaluating the platform:
- Test on throwaway content first. Generate short social media clips before committing commercial projects to the platform. Verify that the output quality and consistency match the claims for your specific use case.
- Check the copyright terms for your jurisdiction. ByteDance terms of service may not align with US copyright protections for AI-generated content. Understand what rights you retain before generating client work.
- Compare output side by side with Veo 3.1 and Kling 3.0. Each model has strengths for different content types. The best AI video workflow in 2026 is increasingly model-per-shot: use whatever produces the best output for each specific scene.
- Watch for independent benchmarks. As of launch, Seedance 2.5 capabilities are ByteDance claims. Independent testing and leaderboard placements will clarify whether the 30-second native generation delivers on its promise in real-world conditions.
Frequently Asked Questions
Is Seedance 2.5 really free?
Seedance 2.0 was offered at free unlimited access through Dreamina. Pricing for 2.5 has not been confirmed at launch, but the expectation is a credit-based system similar to other AI video platforms, with free tier options for lower-resolution or shorter clips.
Can I use Seedance 2.5 for commercial projects?
Yes, but the copyright terms are less favorable than US-based alternatives. Content generated through ByteDance platforms passes through servers subject to Chinese jurisdiction. Review the terms carefully for commercial and client work.
When will Seedance 2.5 be available in CapCut?
ByteDance has confirmed CapCut integration is planned following the initial Dreamina and Jimeng launches. No specific date has been announced, but the integration pipeline typically takes 4-8 weeks after the initial platform release.
Does Seedance 2.5 support real-time generation?
No. The 30-second native clip generation requires significant compute time. Generation wait times have not been officially stated, but similar models typically require 30 seconds to several minutes per clip depending on resolution and complexity.
What are the minimum hardware requirements?
Seedance 2.5 is cloud-based through Dreamina and Jimeng. No local hardware is required beyond a standard web browser. API access, when available, will require cloud compute through Volcano Engine.
How does the unified audio-video generation work with multiple characters?
The model generates synchronized audio for all elements within the scene. For multi-character dialogue, the audio is generated as part of the scene description. Creators can use reference audio clips among the 50 multimodal inputs to specify voice characteristics.
About Barak Schurr
Barak Schurr is a serial entrepreneur who built and exited a major ticketing platform before turning his attention to AI and content. He runs three AI-focused research sites and writes about the tools, workflows, and strategies that let solo creators build real channels — without a crew, a studio, or a Hollywood budget.
Email: [email protected]